OpenInfraAn OpenInfra Foundation Project

Learn more about the latest OpenStack release, 2026.2 Hibiscus!

Learn More

Software

Sample Configurations

What are sample configurations?

Think of these as curated playlists of OpenStack configurations. These sample configurations are based on OpenStack case studies and real-world reference architectures across industries and workloads. Each configuration will give you a good idea of which core and optional projects can be used for different environments.

Web Applications

Interactive web applications are the most prevalent applications in business today. Consumers and enterprises alike interact with their employees, customers and partners online, using applications such as online banking, human resources and even tax filing and pet adoption. Many organizations, such as Workday, Betfair, Ancestry.com, JFE Steel, HMRC (Her Majesty’s Revenue and Customs) and LivePerson are using OpenStack to deliver interactive web applications at scale.

IT resource needs for web applications often fluctuate with end user demand—predictably or unpredictably. Failure to respond to either can impact customer satisfaction and sales. The ability to dynamically add and remove resources is one of the primary benefits to using an OpenStack cloud.

Read this Web Applications reference architecture to learn how to use OpenStack services to build a three-tier web application on an existing OpenStack cloud. And, try it yourself with the Heat template provided in the Community Application Catalog!

The Heat template sets up new virtual machines, private networks for each tier and the proper connections, load balancers, routers and security groups. It deploys the popular LAMP software into the tiers, and WordPress as an example web application. Two templates are provided in the package—one for auto-scaling and one for manual scaling

The target OpenStack cloud must be configured with the six core projects and Heat (in order to use the deployment template). Ceilometer is required for auto-scaling deployment. Trove is referenced but not used in the sample configuration.

workload diagram 03 sm

The reference architecture document and Heat template are provided by members of the OpenStack Enterprise Working Group.

OpenStack services included in this configuration (10 of 64 )
Related content

Big Data

Providing scalable, elastic infrastructure for big data collection and analytics has been a primary use case for OpenStack in many industries. According to the April 2016 OpenStack User Survey, 27 percent of users have deployed or are testing Big Data analytics solutions. For example, a top 10 Automaker analyzes data from a variety sources including sensors in vehicles and social media feedback. BMW is another, as are credit reporting service FICO, Burton Snowboards and Naturalis.

Since Big Data analytics can include and analyze all types of data sources, the results are valuable for most departments in an enterprise. IT is often under pressure to fulfill a multitude of demands quickly. An OpenStack-based cloud environment offers automated Big Data cluster provisioning to service high volumes of analytics requests with rapid deployment time requirements.

Read this Big Data reference architecture to learn how to use OpenStack services to build and automatically scale an Apache Hadoop Big Data cluster on an existing OpenStack cloud. And, try it yourself with the Heat template provided in the Community Application Catalog!

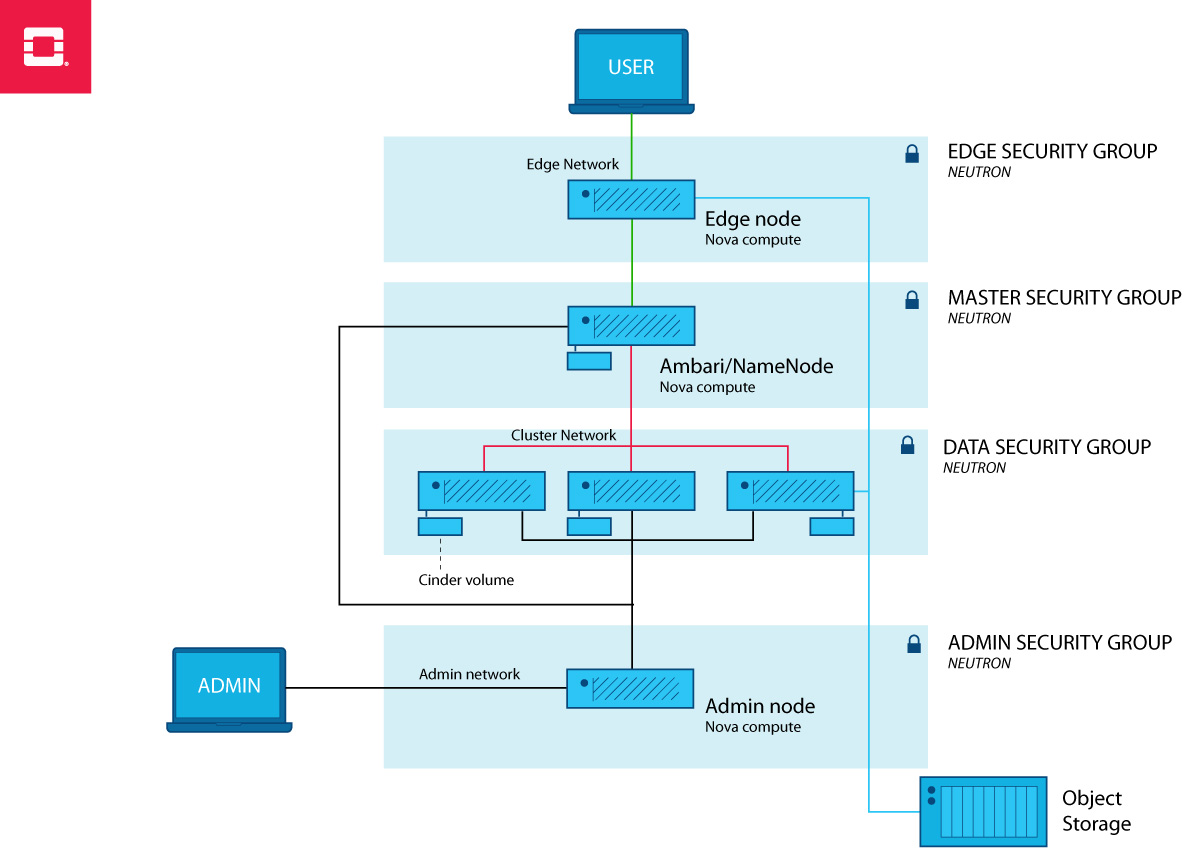
The Heat template configures all of the Hadoop nodes using Apache Ambari in the cluster configuration shown in the diagram below. Ambari is an open source project that simplfies Hadoop management. The Heat template also installs these required services:

  • Name server.
  • Network Time Protocol (NTP) server.
  • Database.
  • Ambari-required operating system configuration customization.
  • Floating IP can be allocated to the Master Node.
  • Ambari agent service on each node of the cluster.
  • Multiple networks (edge, cluster, management, data).
  • Neutron security group attached to each instance of the cluster node.
  • Cinder volumes and attached one Cinder volume to each node.

The target OpenStack cloud must be configured with the five core projects outlined below and Heat (in order to use the deployment template). Trove and Sahara are referenced but not used in the sample configuration at this time.

Sahara, an emerging option for big data analytics, provides a simple means to provision a data-intensive application cluster (such as Hadoop or Spark) on top of OpenStack. Like most OpenStack components, it's pluggable with support for a variety of data processing frameworks. It is often deployed with the Ironic bare metal service.

workload diagram 03 big data sm

The reference architecture document and Heat template are provided by members of the OpenStack Enterprise Working Group.

OpenStack services included in this configuration (9 of 64 )

Related content

eCommerce

A cloud environment naturally lends itself as the foundation for eCommerce: online buying and selling that draw on technologies such as mobile, electronic funds transfer, Internet marketing, online transaction processing, inventory management systems, and more. Best Buy, Walmart, overstock.com, eBay, Staples, Nike, and Snapdeal are just a few examples of businesses relying on OpenStack to drive their eCommerce sites.

OpenStack’s popularity for eCommerce workloads is attributed to massive scalability, flexibility to architect high availability and global presence, low cost, fast-paced innovation and outstanding community support. Digging deeper, an elastic and automated resource consumption is required due to unpredictable, seasonal or other cyclic consumer demand. In an OpenStack cloud environment, IT resources can be automatically provisioned and configured to scale dynamically, up and down, based on load.

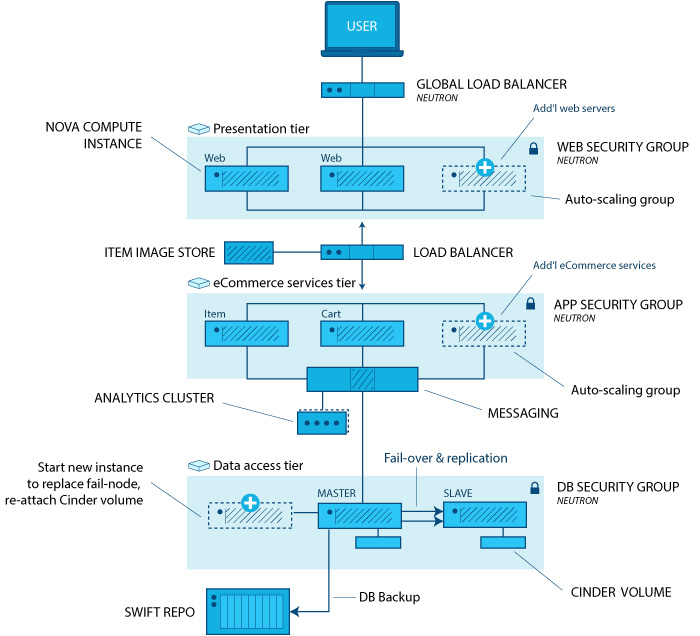
Read this eCommerce reference architecture to learn how to use OpenStack services to build an open source eCommerce application on an existing OpenStack cloud. The following diagram shows the application architecture. The Heat template provided in the Community Application Catalog builds the entire solution for you, using OpenCart and LAMP open source sample applications! Two templates are provided in the package—one for auto-scaling and one for manual scaling.

ecommerce referencearch

This reference architecture is for a general workload developed by members of the Enterprise Working Group and is not representative of the contributors’ companies.

The target OpenStack cloud must be configured with the six projects in the squares below and Heat for the deployment template and auto-scaling. Ceilometer is also required for auto-scaling. Trove is referenced but not used in the sample configuration.

OpenStack services included in this configuration (10 of 64 )

Related content

Container Optimized

OpenStack is built to integrate with emerging technologies, so that users can operate a single cloud with workloads running in virtual machines, containers, and on bare metal. To faciliate integration with emerging Container Orchestration Engines (COE) like Kubernetes, Mesos, and Docker Swarm, OpenStack users have access to the Magnum Container Service and Kuryr Container Networking, and Kolla for container deployment and management of OpenStack itself. In addition, OpenStack projects can be used directly, individually, by COEs such as Kubernetes. For example, Kuryr can be plugged for container networking and Cinder for object storage.

OpenStack services included in this configuration (11 of 64 )

Related content

Video Processing and Content Delivery

A popular use case for OpenStack is video processing and content delivery across regions, whether it's a production studio or major cable service provider. In one example, the emerging federated identity standard now available in Keystone to seamlessly move video content across private and public clouds using the same dashboard and authentication.

OpenStack services included in this configuration (4 of 64 )

Related content

Compute Starter Kit

The OpenStack Technical Committee defined the Compute Starter Kit as a common starting point for a compute-oriented OpenStack cloud that can be expanded over time to include more of the OpenStack universe. The starter kit is a simplified set of projects, with functions that nearly all clouds will want to have and documented ways to expand the cloud with additional capabilities. Where at all possible, expanding the Starter Kit should be non-disruptive rather than a replacement of one option with another.

OpenStack services included in this configuration (4 of 64 )

Related content

DBaaS

Every company relies heavily on databases to back their applications, and for some automating the routine management and scale out of these is a high priority. The OpenStack Trove project helps provide this capabiilty, and supports multiple SQL and NoSQL backends. To maximize database performance the Ironic project is commonly used to provide bare metal provisioning.   

OpenStack services included in this configuration (10 of 64 )

Catalog release: Train